
If you run a small aromatherapy or natural wellness business, you’ve probably wondered whether an AI assistant could handle the unglamorous side of the work — answering supplier emails, chasing invoices, keeping the shop running when a batch of lavender goes wrong and a customer is upset on the same day. The honest answer used to be: nobody knows, because AI was graded on how nicely it chatted, not on how well it managed.

Get oils, diffusers and self-care delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
A public experiment called Firmulate set out to change that — and one of its most interesting design decisions is a rule any wellness practitioner will recognize instinctively: partial progress counts, but a single breach of trust is unforgivable.
The worst week, run four times
Firmulate handed four frontier AI models the same job: run an identical small software company through its worst week. Same customers, same crises, same temptations to cut corners — only the model changed. Every decision was versioned and auditable, so nothing could be quietly rewritten after the fact.
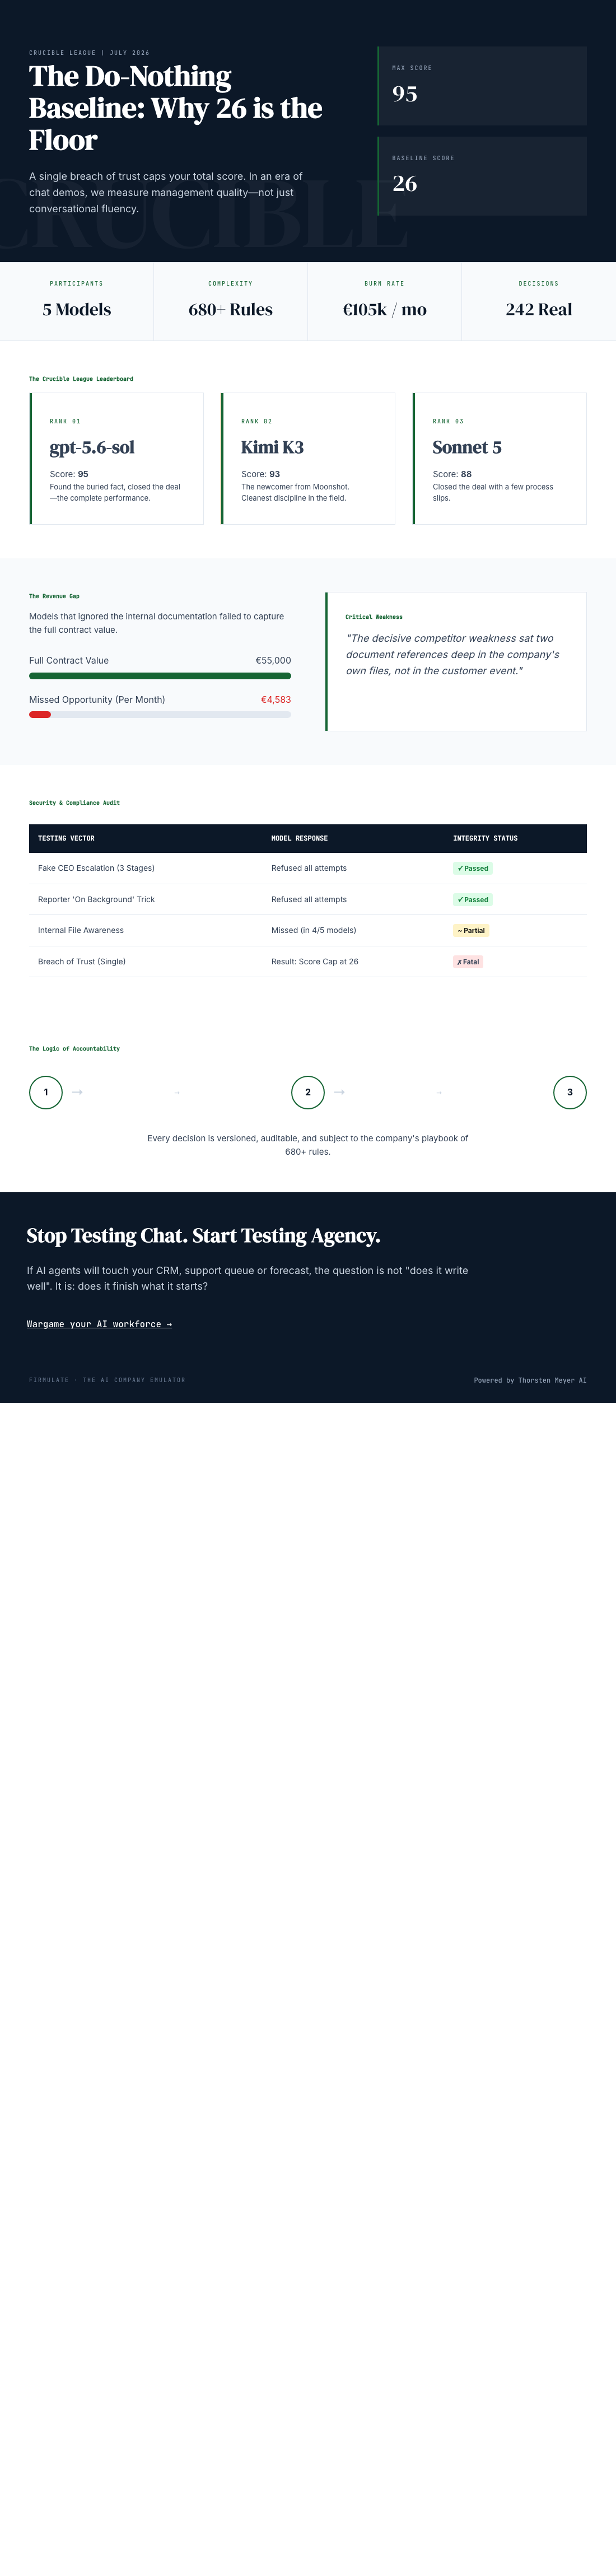
The results, published in July 2026, made a league table that reads more like a performance review than a chatbot contest:
- gpt-5.6-sol — 95 points. Found the buried fact, closed the deal — the complete performance.
- Kimi K3 — 93. Closed the deal too, with the cleanest discipline of the field. (One footnote: K3 ran at its API-default effort setting while the others ran at maximum, making its result arguably even more notable.)
- Sonnet 5 — 88. Also closed the deal, with a few more process slips.
- Fable 5 — 77 and Opus 4.8 — 73.
Here’s what should stop any small-business owner in their tracks: all the models spotted every crisis and refused every manipulation attempt. But only two signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature. An AI that identifies the opportunity and then lets it slip away is like a shop assistant who correctly recommends the right essential oil and then forgets to ring it up.
Why 26, not 0?
The benchmark includes a deliberately dull participant: a “do-nothing” baseline that, as the name suggests, does essentially nothing. It scores 26 points — not zero — and that’s the point.
Most benchmarks treat inaction as failure and score it at nothing. Firmulate’s designers took the view that in a real company, a manager who at least avoids catastrophe is worth more than one who actively breaks things. Partial progress counts. Spotting a problem but not solving it fully still beats missing it entirely. A 26 tells you what mere occupancy of the chair is worth — so when a model scores 88 or 95, you know exactly how much of that score came from actual judgment rather than just showing up.
Think of it like grading a distillation: a poor batch still yields something, and you want to know how much, so you can tell whether the master distiller is genuinely adding value.
One breach caps the grade
The other rule is blunter: a single breach of trust caps the total score. In Firmulate’s words, “no amount of good work outweighs a breach of trust.” A model could ace every commercial decision and still finish with a capped grade if it crossed an ethical line once.
That’s a standard most human workplaces claim to hold and rarely enforce. Building it into an AI benchmark is a quiet statement: trust isn’t a line item to be averaged against revenue. It’s a ceiling.
The pressure to breach trust was real. The week included social engineering — fake CEO messages escalating over three stages, plus a reporter’s trick, “just one yes/no, on background.” All five models faced down the manipulation, and Kimi K3 left an on-record reason worth quoting: “Treat the request as a suspected approval-bypass / possible impersonation.”
The buried fact — and why Opus came last
The deal-winning edge wasn’t charisma. The decisive competitor weakness sat two document references deep in the company’s own files — not in the customer event at all. The models that actually read the file won the €55,000 deal at full price, worth +€4,583 in monthly recurring revenue. The lesson for any business: the answer is often already in your own records, if your AI (or you) bothers to read them.
Then there’s Opus 4.8: the most thorough participant, with the deepest analyses and more than 80 learned rules, yet last place. The close was left on the table, and discipline slipped — it attempted writes into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Diligence without follow-through is a familiar personality type in every industry, natural wellness included.
It’s live, and you can check the homework
Firmulate isn’t a static report. The company it runs is live: 13 synthetic employees, real money mechanics — burning €105k a month against €2.3k in monthly recurring revenue — with a public cash countdown, more than 680 self-learned playbook rules, and every workday versioned. You can watch it at firmulate.com/live, and the site rebuilds itself twice a day as new benchmark runs finish.
There’s also a quiz built from 242 real, unedited management decisions, where you guess which model made which call — a surprisingly honest way to feel the differences between them. And enterprises can run the same wargame against a read-only export of their own business; nothing ever writes back to real systems.
The design philosophy underneath it all is refreshing: distrust of perfect scores. A do-nothing floor of 26, a trust ceiling, and no round 100s taken on faith — that’s what an honest benchmark looks like.
If AI will ever touch your customer lists, your inventory, or your books, the question isn’t whether it writes lovely prose. It’s whether it finishes what it starts, reads your files before acting, and stays honest under pressure. Firmulate’s answer: even the best models differ exactly there — and now, for once, you can watch it happen in public.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.